LLM Systems 15: Distributed Data Parallel Training
0. Recap
- Overall idea: partition the data, distribute the forward/backward
- Parameter Server
- server to update and distribute parameters, worker to get local grad
- NCCL Multi-GPU communication
- using ring and batching to reduce the latency for Broadcast
- Data Parallel Training via All Reduce
- Efficient Ring AllReduce (ScatterReduce+AllGather
1. Distributed Data Parallel Training
Distributed Data Parallel
- Same as Data Parallel
- multiple nodes, each with multiple GPUs
- Create replicas of a model on multiple nodes
- Each model performs the forward pass and the backward pass independently
- Gather average gradients across nodes
- Optimizers run locally (identical)
2. Design and implementation of Distributed Data Parallel
Design Goal of DDP
- Non-intrusive: Developers should be able to reuse the local training script with minimal modifications.
- Interceptive: The API needs to allow the implementation to intercept various signals and trigger appropriate algorithms promptly. The API must expose as many optimization opportunities as possible to the internal implementation.
Setting up the Distributed Process
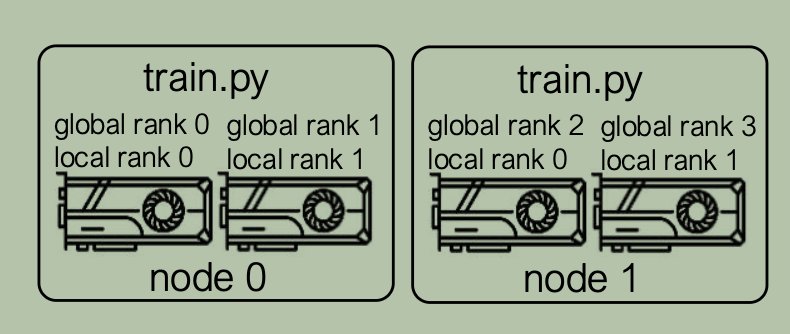
- World size
- total number of processes W
- Global rank
- global process id
- Local rank
- local process id
示例图:
Launch Distributed Processes
The launch.py (torch/distributed/launch.py)
will pass world size, global rank, master address, master port via env
vars, and local rank as a commandline parameter to every instance.
- 关键环境变量:
MASTER_ADDR:主节点(Rank 0 所在机器)的 IP 地址,用于各个进程建立网络连接和握手(Rendezvous)。MASTER_PORT:主节点监听的网络端口号。RANK(Global Rank):当前进程在所有节点中的全局进程 ID(从0到WORLD_SIZE - 1)。WORLD_SIZE:本次分布式训练的总进程数。
Implementation
- Gradient Bucketing
- 具体介绍略,见 paper。
实现代码:
1 | |
3. Code walkthrough: Using DDP in PyTorch
代码链接:link
核心代码即注释:
1 | |
- 启动命令:使用
torchrun启动(例如单机 2 卡训练):
1 | |
- 核心组件要点:
setup_ddp:依赖torchrun注入的环境变量LOCAL_RANK完成设备绑定。DistributedSampler:按卡划分数据集,每个 Epoch 必须执行sampler.set_epoch(epoch)才能确保随机洗牌正常。DDP(model, device_ids=[local_rank]):接管模型梯度通信,在反向传播计算时流水线化发起分桶 AllReduce。if rank == 0::控制打印与保存,防止多卡同时写日志导致死锁或覆盖。model.module:保存模型权重时加上.module,便于后续在单卡/CPU 上载入标准.state_dict()。
4. Summary
- Data Parallel via All Reduce
- Distributed Data Parallel Training
- gradient bucketing
- overlay backward and AllReduce communication
LLM Systems 15: Distributed Data Parallel Training
https://arcsin2.cloud/posts/2026/10/3021269970/